How to Use Seedance 2.0: A Guide for AI Video Creators
Learn how to control camera movement, use references, and create better AI videos in 15 seconds.

Seedance 2.0 is ByteDance's AI video generator for creating multi-shot videos with synchronized audio. It can generate dialogue, sound effects, camera movements, and transitions together, turning a single prompt into a short sequence rather than an isolated animated shot.
But getting a good result depends on more than writing a detailed description. Seedance 2.0 works best when you approach each generation like a short production brief: decide what happens, how the camera captures it, what each reference contributes, and how much action can realistically fit into 15 seconds.
This guide covers how to use Seedance 2.0 in Kapwing, its technical specifications, how to work with image, video, and audio references, and how to write better prompts for character consistency, multi-shot sequences, and realistic movement.
Table of Contents
- What Is Seedance 2.0?
- Seedance 2.0 vs. Seedance 2.5: What's the Difference?
- Seedance 2.0 Specifications
- How References Work in Seedance 2.0
- How to Use Seedance 2.0 in Kapwing
- Seedance 2.0 Workflows and Examples
- Frequently Asked Questions
What Is Seedance 2.0?
Seedance 2.0 is a multimodal AI video generation model developed by ByteDance, the company behind TikTok and CapCut. Released in February 2026, it supports text-to-video, image-to-video, reference-guided generation, and native audio.
Unlike AI video generators designed primarily for single continuous shots, Seedance 2.0 can interpret a sequence of camera instructions and generate several connected shots within one clip. It can also generate dialogue, ambient sound, music, and action-matched sound effects alongside the visuals.
Its most useful capabilities include:
- Multi-shot generation: Create several shots with camera changes and transitions in a single generation.
- Native audio and lip sync: Generate spoken dialogue, music, ambient sound, and sound effects alongside the video.
- Multi-reference generation: Use images, videos, and audio files to guide visual consistency, movement, pacing, and sound.
- Character and action control: Describe interactions between characters, coordinated movement, and specific camera directions.
Seedance 2.0 vs. Seedance 2.5: What's the Difference?
Seedance 2.5 builds on 2.0 with longer generations, expanded reference capacity, and stronger continuity across complex sequences. However, those changes don't necessarily make 2.0 obsolete.
9 images · 3 video · 3 audio
Images, video and audio
Limits shown reflect Kapwing's model integrations, not every third-party provider.
In our side-by-side testing, Seedance 2.0 sometimes followed precise camera instructions more reliably than 2.5, especially when a prompt specified a locked camera position or a hard cut. It also produced convincing character consistency and handling complicated physical interactions.
For short, deliberately composed shots, Seedance 2.0 remains a useful option. The important constraint is its 15-second generation window, which changes how you structure your prompts.
Seedance 2.0 Specifications
Before generating, it helps to understand Seedance 2.0's technical limits.
They determine how much action you can fit into a clip, which references you can use, and how you should prepare your assets.
Seedance 2.0, at a glance
The practical limits to design around before writing your prompt.
4 seconds minimum
15 files maximum across all reference types
Three practical considerations matter most:
1. Fifteen seconds is the maximum, not the recommended duration. A simple product shot might only need five seconds, while a three-shot commercial needs more time to establish each composition.
2. Fifteen references is a capacity limit, not a target. Every additional asset introduces information Seedance needs to interpret. Two or three well-chosen images can be more useful than nine nearly identical references.
3. Multi-shot generation is not the same as unlimited video editing. Seedance 2.0 can generate multiple shots and interpret reference footage, but it does not offer the same targeted editing and extension capabilities described for 2.5. For longer sequences, generate separate clips and assemble them in an editor.
How References Work in Seedance 2.0
One of Seedance 2.0's most useful features is its ability to combine image, video, and audio references in a generation.
Instead of asking the model to invent every detail, you can supply existing assets that establish how a character looks, how a scene moves, or how its soundtrack should feel. Each reference type serves a different purpose.
Give every file one job.
References are clues, not commands. Assign each file a specific purpose so it doesn't accidentally change the rest of the scene.
Defines the look.
Use a portrait, character sheet, product photo or scene image to establish visual details.
Suggests motion.
Guide camera behavior, pacing or action. Seedance interprets the clip; it does not copy motion exactly.
Guides sound.
Supply a sound reference or describe dialogue, ambience and effects directly in the prompt.
#image_1 defines the woman's face and red jacket. #image_2 defines the café interior only. #video_1 guides the slow tracking camera movement; do not copy its subject.How to Use Seedance 2.0 in Kapwing
You can access Seedance 2.0 through Kai, its browser-based AI video assistant.
The best workflow depends on how much of the finished video you already know. There are three main approaches.
How to Generate a Seedance 2.0 Video With Text-to-Video
Text-to-video is the simplest workflow. You supply a description without attaching any visual references, and Seedance generates the subject, environment, action, camera movement, and audio.
It's useful for testing ideas, creating establishing shots, and generating scenes where the exact appearance of a character or object is less important.
1. Describe the video you want.
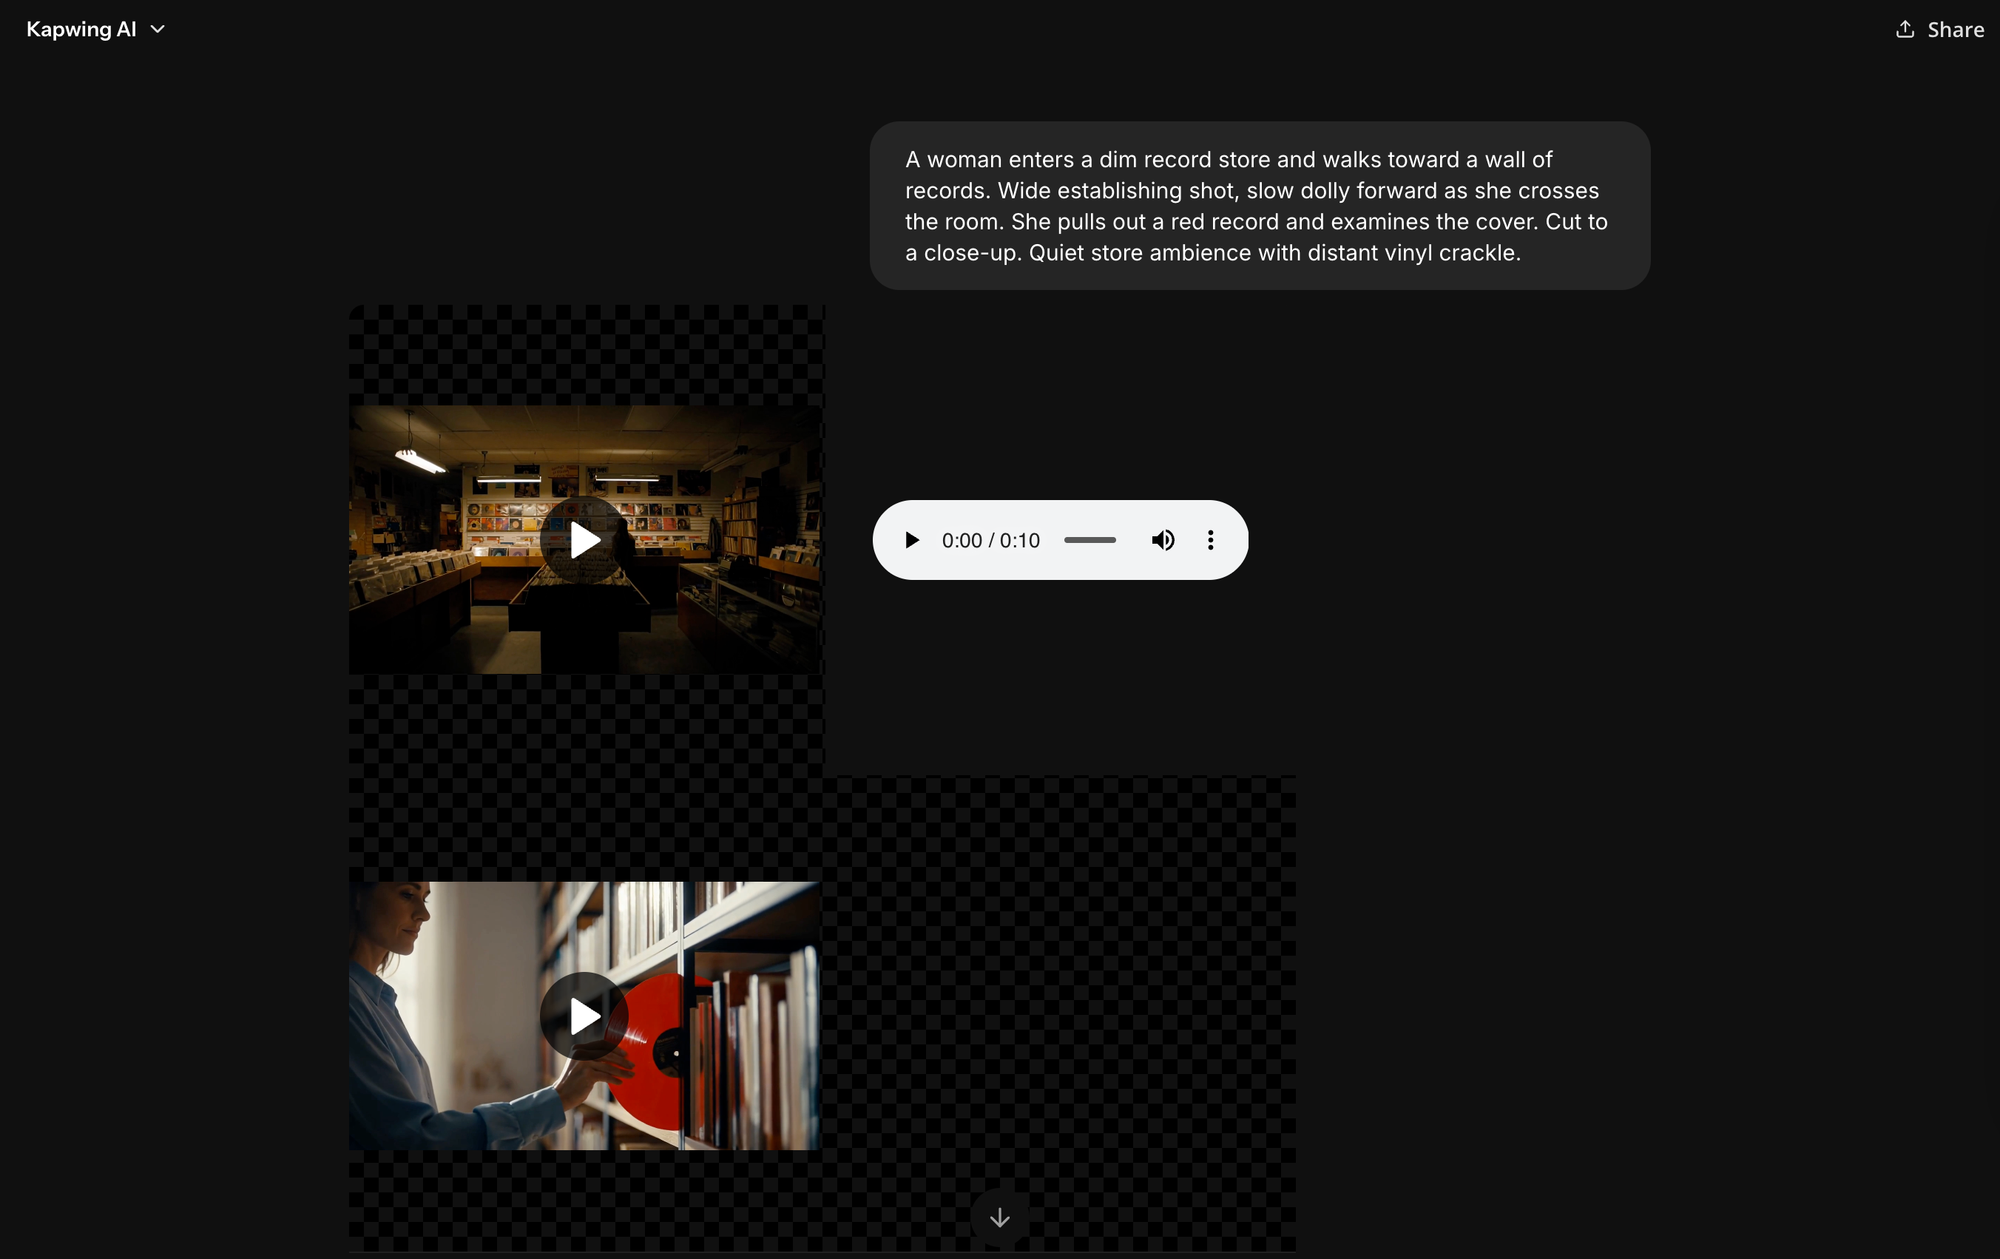
In the prompt box, specify the subject, setting, action, and camera behavior. Add audio instructions if sound matters to the scene. For example:
A woman enters a dim record store and walks toward a wall of vinyl records. Wide establishing shot, slow dolly forward as she crosses the room. She pulls a red record from the shelf and examines its cover. Cut to a close-up of the record in her hands. Warm overhead lighting, quiet store ambience, distant vinyl crackle. 16:9, 10 seconds.

To write a high-quality Seedance prompt, make sure to describe:
- Subject: Who or what appears in the video.
- Setting: Where the scene takes place.
- Action: What happens and in what order.
- Camera: Shot size, angle, movement, and framing.
- Timing: How actions or shots are distributed across the available duration.
- Audio: Dialogue, ambience, sound effects, or music when relevant.
- Constraints: Details that must remain consistent or things Seedance should not change.
Build a better 12-second video.
Explore each part of a Seedance 2.0 prompt, then edit and copy the full example. No 30-second timelines or end-frame instructions.
Subject + action
Tell Seedance who appears, what they do, and how their action progresses. A concrete action is more useful than a string of stylistic adjectives.
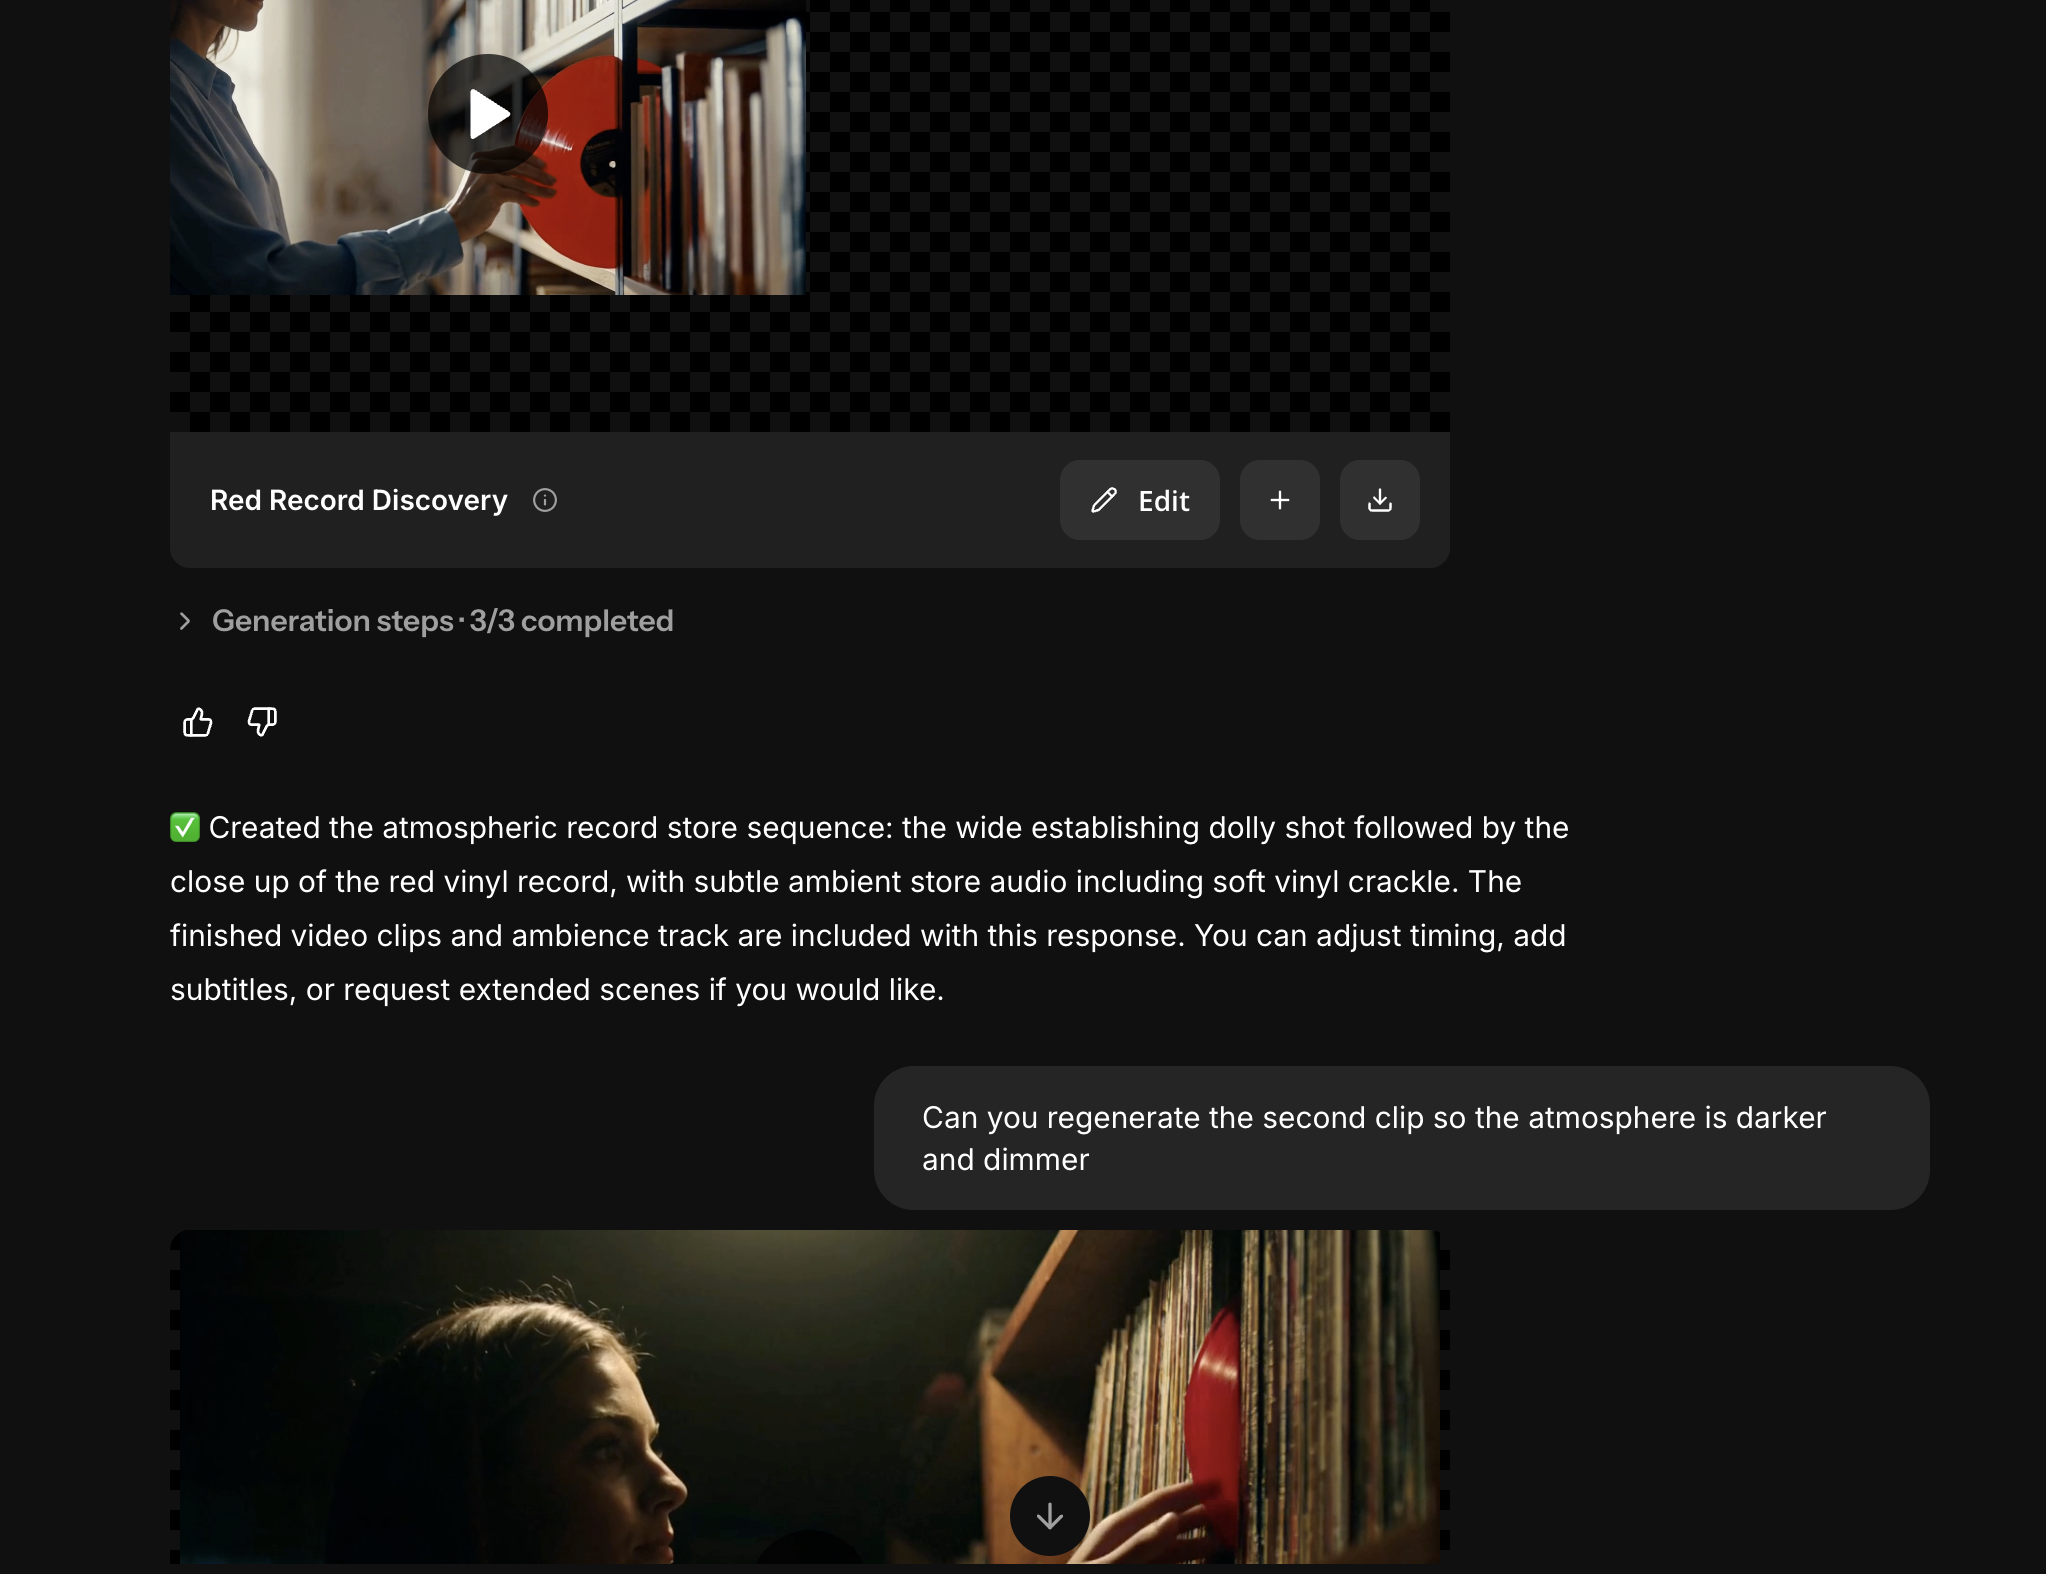
2. Generate and iterate.
Treat the first generation as a diagnostic pass. Watch the clip from beginning to end at least once before changing anything. Then evaluate it across five layers:
- Identity and appearance: Did characters, products, clothing, and other important visual details remain stable?
- Motion and camera: Did subjects move correctly? Did Seedance follow the requested camera controls, speed, framing, and shot changes?
- Reference adherence: Did each image, video, or audio reference influence the property you assigned to it, and only that property?
- Audio-video coordination: Did dialogue, lip movement, sound effects, music, and visible actions line up?
This distinction matters because different failures require different fixes:
- Instruction failure: Seedance consistently interprets an instruction differently from what you intended. Rewrite that instruction more concretely.
- Constraint conflict: Two parts of the prompt or two references are asking for incompatible things. Remove or prioritize one.
- Information gap: Seedance is being asked to preserve something it cannot actually see. Add a reference that exposes the missing information.
- Temporal overload: Too many actions, camera moves, cuts, or spoken lines are competing for the duration. Reduce the sequence or give it more time.
- Generation variance: The instructions are clear and the setup has produced good results before, but this particular generation failed. Regenerate.
How to Generate a Seedance 2.0 Video With Image-To-Video
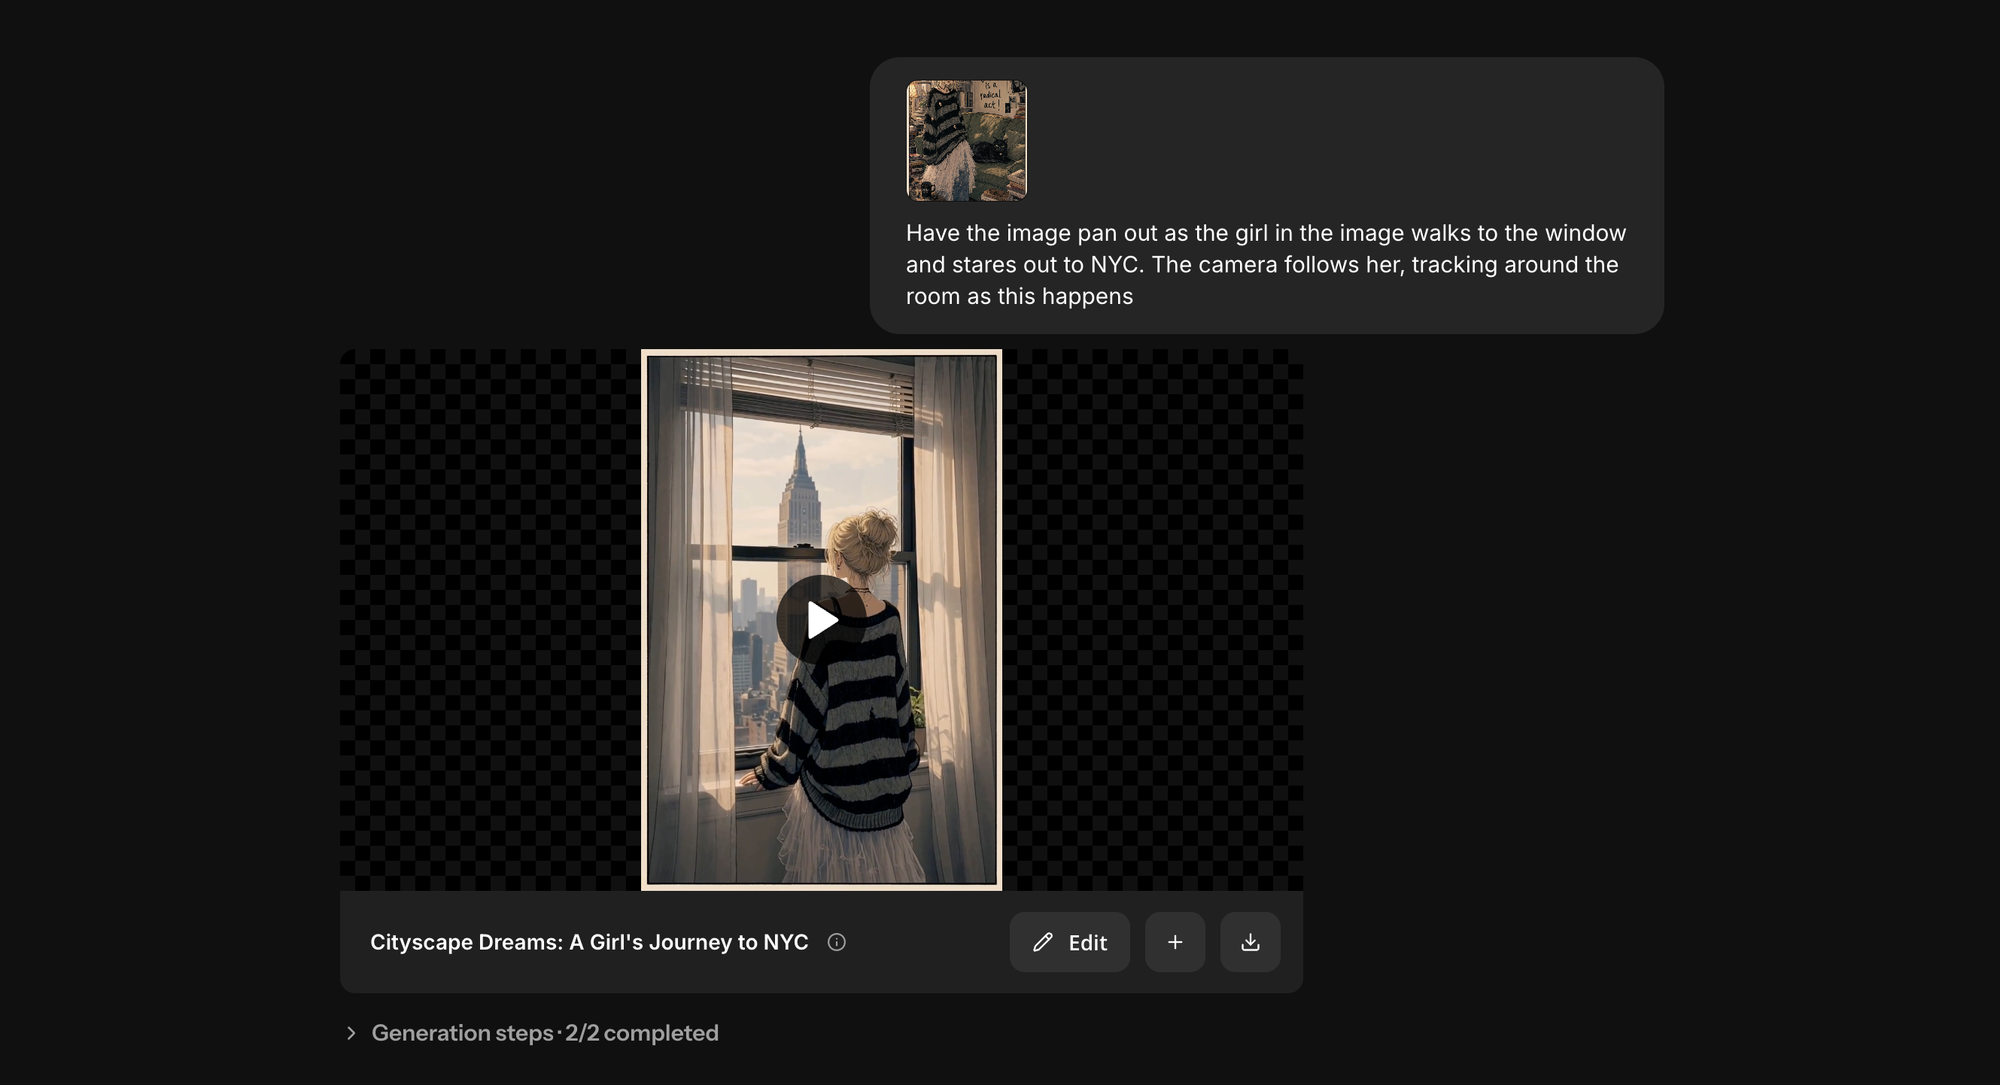
Adding an image changes Seedance's job. Instead of inventing the entire scene, the model begins with an existing visual and infers how that it should be animated.
That makes image-to-video particularly useful when composition or appearance is important: animating an image, adding movement to a shot, or turning a landscape into a drone-style shot.
1. Step 1: Choose a start frame
The start frame establishes the initial subject, environment, lighting, and composition. Choose an image that provides enough information for the movement you want.
For example, a three-quarter product photograph is often more useful for a camera orbit than a flat frontal view, because it exposes more of the object's shape.

In general, look for:
- A clearly defined subject
- Visible depth and spatial separation
- Enough room around the subject for the intended movement
- Good detail in anything that needs to remain recognizable
- Consistent lighting

2. Describe how the image should move.
You don't need to repeat everything visible in the reference. Instead, focus on information the still image cannot communicate: movement, timing, camera behavior, and sound.
Use the attached serum bottle image as the start frame. Begin with the bottle resting on pale marble. The camera makes a slow clockwise orbit of approximately 20 degrees while soft window light moves across the glass. Preserve the bottle's proportions, black cap, and amber color. Quiet room ambience, no music. 16:9, 6 seconds.
3. Generate and check visual consistency.
Pay attention to product proportions, facial features, clothing, and any details that should remain unchanged.
Seedance 2.0 does not support end-frame generation. If you need a clip to finish on an exact image, generate the shot and use Kapwing's editor to create the final transition, or choose 2.5, which supports start-and-end-frame control.
How to Generate With Multiple Image, Video, and Audio References
Multi-reference generation is where Seedance 2.5 differs most from a conventional image-to-video model.
A reference can provide a source of truth; for example, you might use one image for a character's face, another for their outfit, a video for camera movement, and an audio file for dialogue generation.
1. Build the reference set.
Before uploading anything, identify which properties of the finished video need to come from an existing source. For example:
- @Image1: Character identity
- @Image2: Outfit
- @Image3: Product appearance
- @Video1: Camera movement
- @Video2: Character action or choreography
- @Audio1: Dialogue or vocal delivery
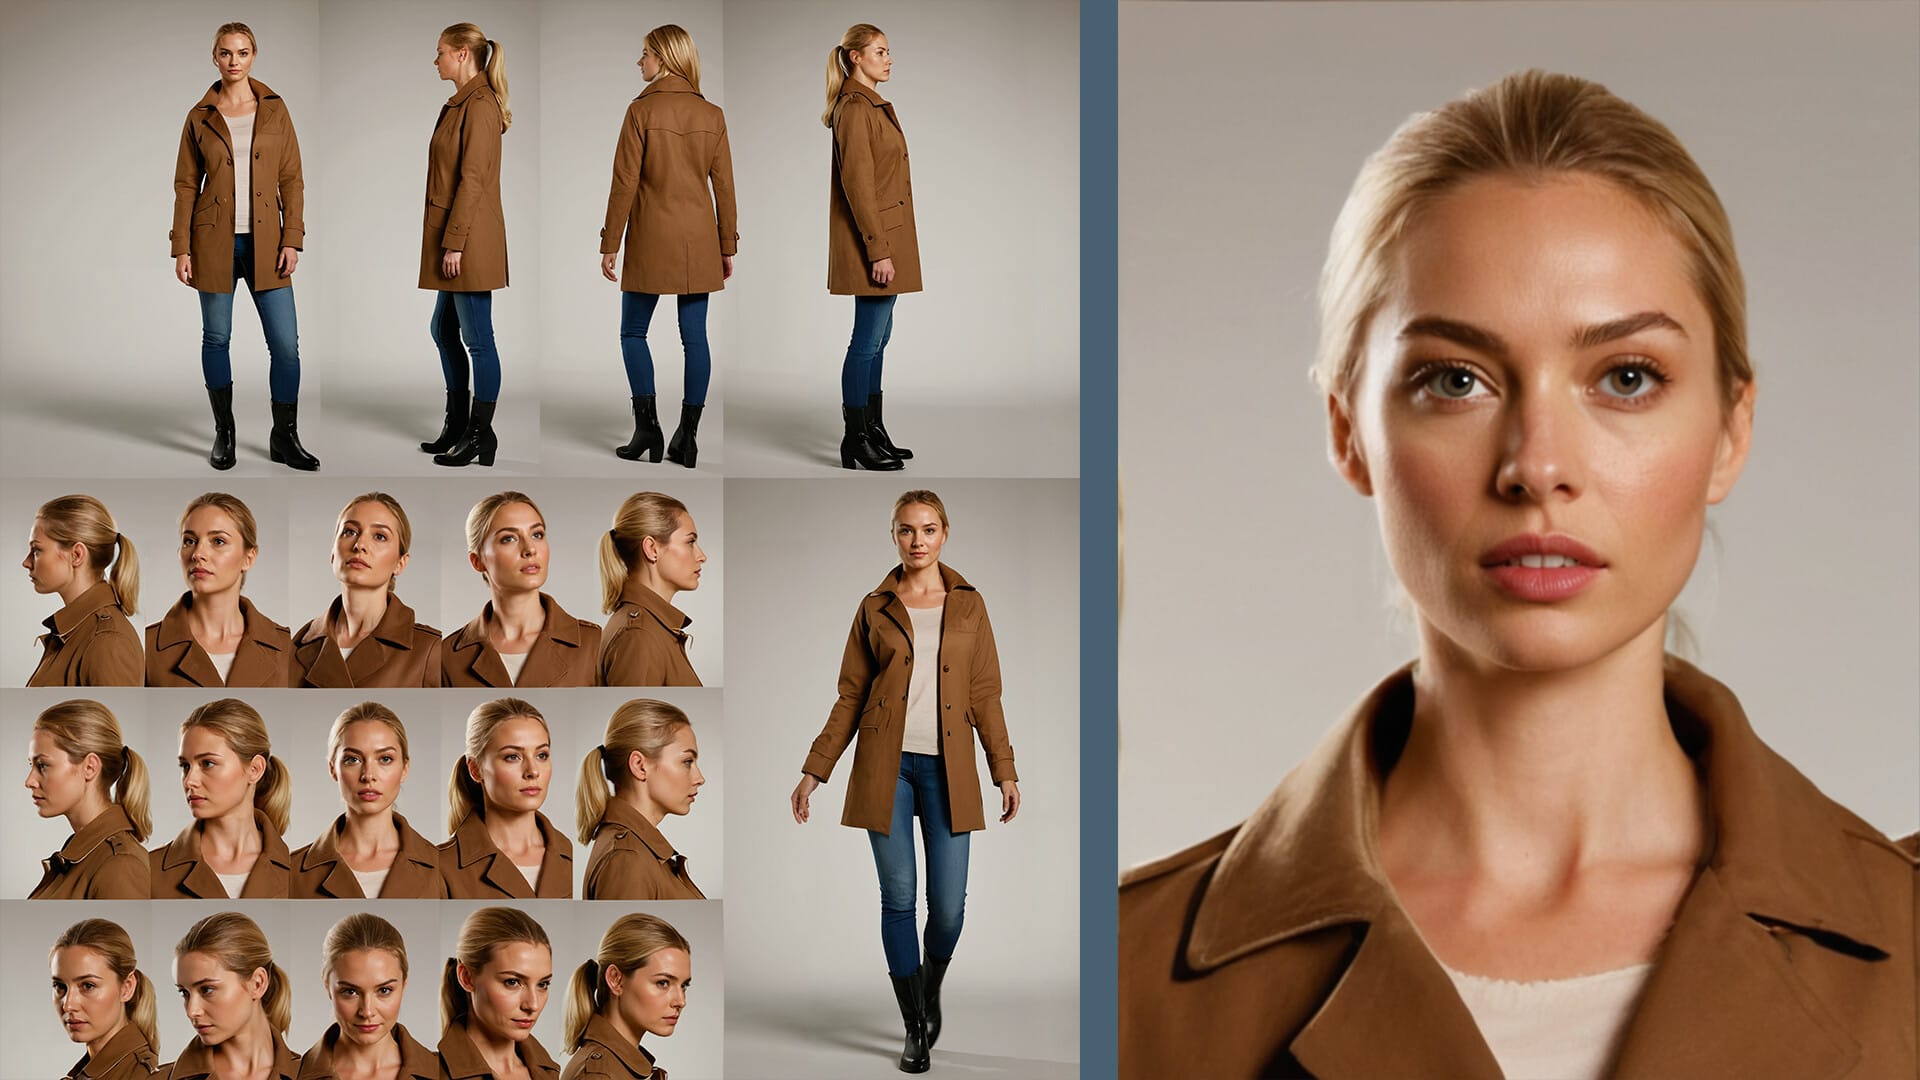
Character sheets or storyboards can be useful here to add into the reference set.
If @Image1 already shows the character's face and outfit clearly, a second image showing almost exactly the same information may add little useful control. Worse, small differences between the two references can create ambiguity.
2. Assign each reference a specific role.
Uploading an asset doesn't tell Seedance which information inside it matters. Instead of:
Use @Image1, @Image2, and @Video1 as references.
Write:
@Image1 defines the woman's face, hair, and identity. @Image2 defines her outfit only. @Video1 defines camera trajectory and pacing only; do not copy its subject, environment, lighting, or color palette.
This reduces one of the most common problems in multi-reference generation: a reference unintentionally the generation result.

3. Separate reference instructions from the new scene.
Once each input has a role, describe the video you actually want to create separately. For example:
@Image1 defines the woman's face and identity. @Image2 defines her outfit only. @Video1 defines camera trajectory and pacing only; do not copy its subject or environment.
Generate the same woman walking through a bright contemporary art gallery. Begin in a medium-wide shot and reproduce the slow backward tracking movement from @Video1 as she walks toward camera. She stops in front of a large abstract painting and looks up. Preserve her identity and outfit throughout.
Seedance 2.0 Workflows and Examples
Once you understand how Seedance handles references and prompts, the most useful way to work with it is to build each generation around the specific information the model needs to preserve.
The examples each uses a different combination of images, video, audio, timing, and preservation constraints depending on the production problem.
Create a Multi-Shot Product Ad
Product videos are a good fit for Seedance 2.5 because you can move through several shot types without regenerating the product separately for every shot.
Start with a clean product reference that clearly shows the details that need to survive the sequence.
Seedance 2.0 Product Ad Video Example Prompt
@Image1 defines the serum bottle, including its exact shape, amber glass, black cap, label, and proportions. Preserve these details throughout.
0–8s: Wide hero shot of the bottle on pale marble. Slow push forward as warm window light moves across the glass.
8–18s: A hand enters from the right and slowly rotates the bottle. Maintain its exact geometry and label.
18–25s: Cut to a tight macro shot of the label. Shallow depth of field, soft room tone and subtle glass-on-stone sound.
Keep a Character Consistent Across Multiple Shots
Choose one image as the canonical source for identity. If that image doesn't clearly establish the full outfit, use a second image specifically for those properties.
The difficult part isn't generating the first shot; it's carrying that character consistency through multiple shots.
Seedance 2.0 Character Consistency Example Video Prompt
SCENE CONTEXT: A four-member East Asian girl group in a super-fast hard K-pop hip-hop piece, told as one linear story in four acts: ORIGIN (a retro TV, a plunge into the screen, a retro-futuristic cockpit, space, a surreal dentist pocket reached through an eye), ARRIVAL (descent to Earth, a night airfield landing, exit in spacesuits), THE GAUNTLET (a huge crowd of fans and reporters they push through while performing), and THE DANCE (the beat drops as they break free and perform a group dance high on a tower, filmed both cinematically and by a circling reporter news helicopter). The clip lives in polished cinematic quality except during the gauntlet and the helicopter aerials, which are degraded reporter-camera footage. No cyclorama, no neon anywhere, no national flags.
MEMBER COUNT LOCK (critical): The group has exactly four members, never five, never six. No fifth member, no extra unnamed dancer, no background double, no duplicated or cloned member. Each of the four appears once and only once in any frame, no mirror, glass, or reflection showing an extra copy.
DUAL-QUALITY SYSTEM (critical): [FILM] is polished modern digital cinema, clean, sharp, stable, glossy, graded, deep glossy blacks, the default for the whole clip. [REPORTER CAM] is a degraded early-2000s cheap phone, camcorder, or news-helicopter look, heavy VHS-grade compression, chunky macroblock artifacts, smeared low resolution, muddy color, blown-out highlights, constant handheld or chopper jitter, crude digital crop-zoom punches, autofocus hunting, rolling-shutter wobble. The degradation appears only in REPORTER CAM beats and never leaks into FILM beats.
TRANSITION MOTIF: Alongside hard cuts, creative MATCH CUTs on round shapes and through eyes, a round CRT screen, a round porthole, a round dentist lamp, a planet disc, and a member's eye all rhyme. The camera pushes into the round shape or into an eye until it fills frame, then emerges in the next scene.
FORMAT MODE: Controlled twenty-four-beat rapid sequence, real-time motion, hard cuts and a few match cuts on the beat, average beat around 1.25 seconds. Every beat has a moving camera and hard motion, no static holds. Each beat tagged FILM or REPORTER CAM.
ACTION TIMING, approximately 152 BPM hard trap-drill K-pop, cuts land on the beat.
ACT 1, ORIGIN: 0.0s to 1.25s, FILM, an old wood-panel CRT glows in a dark room, camera pushes into the screen until white fills frame, match cut into round screen. 1.25s to 2.5s, FILM, cockpit reveal, the four in white spacesuits hitting a unison pose. 7.5s to 8.75s, FILM, one member floats in zero gravity in full body against the star-field, the camera orbiting her floating form, ending pushed toward her eye, match cut into her pupil. 8.75s to 10.0s, FILM, out of the pupil into a bright clinical dental room, one member alone in the dentist chair, match cut through the round lamp.
ACT 2, ARRIVAL: 10.0s to 11.25s, FILM, the ship punches down through cloud, hot orange heat glow raking the hull. 12.5s to 13.75s, FILM, the gear strikes the tarmac, steam and smoke billowing.
ACT 3, THE GAUNTLET: 13.75s to 15.0s, REPORTER CAM, degraded phone POV from behind the crowd barrier, violent handheld shake, other phones jutting into frame. 15.0s to 16.25s, FILM, the ramp lowers, the four appearing backlit in the doorway in spacesuits. 17.5s to 18.75s, FILM, the lead member walks the four across the floodlit tarmac straight toward camera, exactly four in a line. 20.0s to 21.25s, FILM, camera body-locked to the lead member as she pushes forward through the packed crowd.
ACT 4, THE DANCE (tower, card outfits, no spacesuits): 21.25s to 22.5s, FILM, all four burst into clear floodlit space and hit a hard unison hit as the beat drops, ending on a hard close of one member's eye, match cut into eye. 22.5s to 23.75s, FILM, out of the eye onto a tall open steel platform atop a broadcast tower high above the night city, the four now in their card outfits dance hard in a line, exactly four, no double. 23.75s to 25.0s, REPORTER CAM, degraded news-helicopter footage, the four small on the distant tower platform dancing. 28.75s to 30.0s, FILM, final freeze, the four land the final unison pose, camera cranes up and away for the last frame, exactly four figures.
PHYSICS: Real ground contact and weight transfer on every step, true jaw and lip mechanics on the rap, hair and cloth lag on spins and whips. Zero gravity in space, hair and necklace drift weightless with slow inertia. The ship carries real mass on descent and landing, gear compresses, steam billows. The crowd has real bodies and mass, fans and reporters press, sway and reach with true weight. FILM camera moves carry real inertia, REPORTER CAM motion is human or chopper chaos, real hand shake, stumble, jostle, never gimbal but plausible. Exactly four members and five fingers per hand.
LIGHTING: FILM beats lit for grounded cinematic contrast, never murky, no neon anywhere. TV room near-black with CRT glow only. Cockpit lit in cool cyan and warm amber. Space is black star-field with cool blue-white rim light. Dentist bright clinical white with one cold-blue accent. Tower platform cool moonlight plus hard tower floodlights plus warm distant city glow. REPORTER CAM beats show the same physical lights through a cheap sensor, crushed muddy shadows, harshly blown highlights.
AUDIO: Music added in post, no generated vocals, no words, no melody from the model. Mouth motion is rap cadence, not synced to specific words. Diegetic bed only: CRT hum, ship thruster rumble, steam hiss, crowd roar, helicopter rotor thrum under the aerials.
POSITIVE LOCKS: The group is exactly four members across all beats, no fifth member, no duplicate or cloned member. Faces and hair stay fully consistent with the four reference images. Wardrobe by act: spacesuits in origin, arrival, and gauntlet, card outfits on the tower. Spacesuits carry no national flags, no flag patches. No neon anywhere. The dual-quality system is strict, FILM beats stay fully clean, REPORTER CAM beats carry the full degraded look, the two never mix in one shot. Real-time 24fps, no slow motion, no speed ramps, no ghosting or trails.
Turn a Storyboard or 3D Blockout Into Finished Video
A rough storyboard, animatic, or 3D blockout can establish where subjects are positioned, how they move, and how the camera travels.
Separate references can then define what those subjects and environments should actually look like.
Seedance Storyboard to AI Video Prompt
Use the reference storyboard to make a full 30 second animation movie. Work through all fifteen panels in order, giving each panel roughly two seconds of screen time so the story plays out at a steady, unhurried pace across the whole thirty seconds. Do not rush the beats and do not finish early.
Do not render any text, numbers, letters, timecodes, panel numbers, captions, watermarks or on-screen graphics of any kind. Clean frames only.
Audio: Diegetic sound only — natural ambience, environmental foley, and subject-driven sound.
Create a UGC-Style Ad
UGC-style videos need to feel casual while simultaneously maintaining a character, product, spoken performance, and natural camera behavior.
For product-focused UGC, also watch for reference competition between the creator and the object. If the product needs an exact label or package design, use a clean reference rather than relying on the bottle visible in the character image.
Seedance 2.0 UGC Style Video Example Prompt
Vertical 9:16 UGC video, 30 seconds total, 24fps, shot on iPhone 14 Pro, authentic phone-camera look, handheld selfie framing from her seat for the whole video, arm's-length wobble, tiny refocus moments, soft even cabin lighting, natural vlog pacing, 8 shots, one consistent framing with small variations, the first shots shake with real turbulence, then the frame settles as the flight smooths out.
Cast: the young woman from the reference image, face fully visible and matching exactly in every shot, fair skin, shoulder-length pastel-pink wavy hair under a burgundy beanie with a small silver star pin, blue eyes, small stud earrings, natural minimal makeup. Her acting is understated and real, she blinks at a natural rate, reactions arrive a half-beat late, smiles start small and grow, she glances away from the lens and back mid-sentence, and she keeps her voice down like someone slightly self-conscious about filming on a plane, no wide eyes, no exaggerated faces, no performing.
Background passengers, realistic, alive, never NPC-like: scattered through the blurred cabin, a middle-aged man asleep against a window with his head tilted and mouth slightly open, a woman in her 30s reading a paperback, an older man scrolling a phone with reading glasses low on his nose, a young woman with headphones gazing out the window. Each moves subtly and independently, nobody looks at her or her camera, nobody reacts in sync.
Product: the exact box from the reference, BAKEY Chocolate Chip Cookie Dough, The London Bakehouse Co, Ready to Bake, red box with cream lettering and the cookie photo, sitting on her tray table.
Location: the airplane cabin from the reference, navy leather seats with white GGS AIR headrest covers, grey armrests, oval windows with soft daylight. Seating geometry fixed for every shot: she sits in the aisle seat, the aisle at her left shoulder, the seats to her right toward the window occupied by the sleeping man.
Segment 1 (0-10s): Shot 1, Turbulence Hook (0-4s), handheld selfie, the frame shaking, the cabin rattles through rough turbulence, she grips the armrest with one hand, phone wobbling in the other, and talks to the lens through it in a tight controlled voice: "So we are currently being shaken like a snow globe." Shot 2, It Settles (4-7s), same framing, the shake easing beat by beat until calm, she exhales slowly and says: "Okay. We're fine. Everything's fine." Shot 3, The Pivot (7-10s), she looks down at her tray table, lifts the red box into frame, pats it twice, and says: "And this survived, which is all that matters."
Segment 2 (10-20s): Shot 4, The Open (10-13.5s), closer selfie, she folds the box open and brings out one golden cookie, no speech. Shot 5, First Bite (13.5-17s), she takes an unhurried bite, chews for a real moment, and says: "Okay, that's actually really good." Shot 6, The Detail (17-20s), closer on the cookie, she breaks it in half slowly and murmurs: "Look at those chocolate chunks."
Segment 3 (20-30s): Shot 7, The Verdict (20-25s), same selfie framing, relaxed, she gives her recommendation: "These are Bakey, by the way. Honestly the best thing I packed for this trip." Shot 8, Quiet Outro (25-30s), no more words, she finishes the half in two calm bites, dusts her fingertips, tucks the box flap closed, and lets her head rest back against the seat, the frame holds calm and still, no product packshot.
Material realism: the turbulence reads true, the handheld frame jolts in irregular bumps, hair and tie sway with the plane's motion. The calm afterward is equally true, the frame's motion decays gradually, not instantly. The cookies are golden with matte cracked surfaces, soft flex at the bite, dark chocolate chunks glossy, real crumbs on the napkin. Skin is real human skin, visible pores, natural sheen, no plastic smoothness.
Audio: no music, she speaks on camera with accurate lip-sync. The soundscape carries the story, rough rattling cabin, creaking bins and a seatbelt chime under Shot 1, the rattle decaying into smooth engine hum in Shot 2, the cardboard flick in Shot 4, the soft cookie snap in Shot 6. Her voice: young American accent, warm and low-key, relaxed unhurried pace, every line a complete finished sentence, no trailing off. All speech ends by 25s.
Consistency rules: her face stays the same person from the reference in every frame. She stays in the same aisle seat for the entire video, no seat changes, no teleporting. Turbulence exists only in Shots 1-2 and never returns. The background passengers keep their same seats, faces, clothes and activities in every shot. The BAKEY box lettering stays sharp and correctly spelled whenever visible. The cookie only shrinks, whole in Shot 4, bitten from Shot 5, two halves in Shot 6, finished in Shot 8, never regrowing. Exactly five fingers per hand. No on-screen text or captions, no product packshot at the end, the video ends on her.
Frequently Asked Questions
Is Seedance 2.5 better than Seedance 2.0?
For more complex production workflows, Seedance 2.5 is a significant upgrade. Its 30-second generation window, larger multimodal reference capacity, stronger continuity, native audio-video generation, and editing capabilities make it better suited to multi-shot sequences rather than isolated clips.
Visually, the biggest difference is often continuity rather than raw image quality: 2.5 is better equipped to carry characters, scenes, motion, and camera language across a longer sequence without making every shot feel like a separately generated clip.
Does Seedance 2.0 support start and end frames?
Seedance 2.0 supports start frames in Kapwing, but not end frames. You can provide an initial image and describe how the scene should move, but you cannot lock the final generated frame to a second image using Seedance 2.0 in Kapwing.
How many reference images can Seedance 2.0 use?
In Kapwing, Seedance 2.0 supports up to nine image references, three video references, and three audio references, with a maximum of 15 reference files across the three types.
Can Seedance 2.0 copy motion from another video?
Seedance 2.0 can use video references to guide movement, camera behavior, and pacing, but it does not provide strict one-to-one motion transfer in Kapwing. For precisely copying choreography or a reference performance, use a dedicated motion-control model.
Can Seedance 2.0 edit existing videos?
Seedance 2.0 is primarily used for generating videos from text, images, and references. It does not provide the same targeted generative video-editing features as Seedance 2.5. However, videos generated with Seedance 2.0 can be trimmed, combined, captioned, resized, and edited in Kapwing.
Read next

How to Edit Videos Like a YouTuber

Claude Video Editing: How to Translate and Dub Videos (Full Setup)